Decision Mechanics

Insight. Applied.

  • Services
    • Decision analysis
    • Big data analysis
    • Software development
  • Articles
  • Blog
  • Privacy
  • Hire us

Data cascades—the impact of data mismanagement

May 3, 2021 By editor

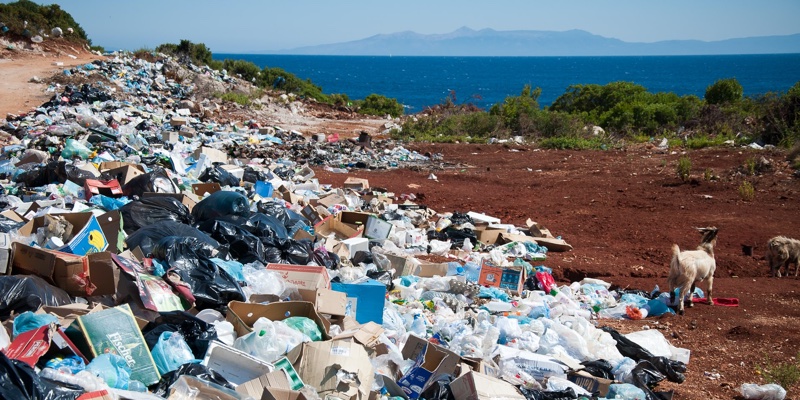
mount of garbage

It’s data science, folks. It lives and dies by the quality of the data.

Google Research recently published a paper where they argue that machine learning solutions are being undermined by a lack of focus on data quality issues. They note that

[…] data is the most under-valued and de-glamorised aspect of AI

and that data is

[…] viewed as ‘operational’ relative to the lionized work of building novel models and algorithms.

Ironically, data science arose from statisticians’ disinterest in the collection and wrangling of data. Revisiting the sins of the father, I guess.

The Google researchers point to the prevalence of data cascades—upstream events that have compounding negative effects on project outcomes.

92% of AI researchers interviewed for the study had suffered from a data cascade.

Four categories of data cascade were identified.

  • Interacting with physical world brittleness
  • Inadequate application-domain expertise
  • Conflicting reward systems
  • Poor cross-organisational documentation

All of these issues conspire to rock the very foundations of the models we increasingly rely on.

Data quality is hard to get right. It’s a much harder problem than model development. And, while the specific choice of model is often unimportant, the same is never true for the data that is fed into it.

One reason data quality to so hard to achieve and maintain is that it’s a process problem—often involving multiple organisations and stakeholders.

As the authors of the study lament,

Data quality carries an elevated significance in high-stakes AI due to its heightened downstream impact, impacting predictions like cancer detection, wildlife poaching, and loan allocations.

We need to stop fetishising algorithms at the expense of data. Tutorials on machine learning libraries and Python are smeared across the Internet. We need to promote and reward good data hygiene.

The consequences of continuing to undervalue data work are stark.

Garbage in, garbage out.


Photo by Antoine GIRET on Unsplash
Filed Under: Artificial intelligence, Data analysis, Data science Tagged With: data cascade, data quality

Guess the Correlation

April 14, 2021 By editor

People find it difficult to intuitively gauge the level of correlation between variables.

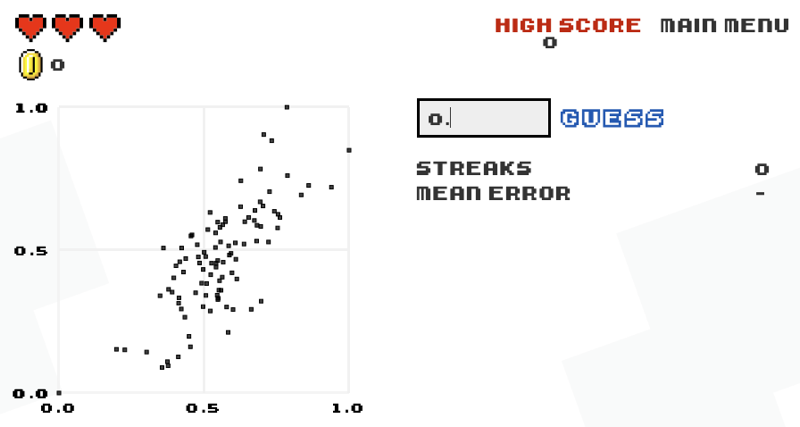
Guess the Correlation is an 80s-style video game that lets you flex your estimation muscles.

Just be aware that it doesn’t seem to present negative correlations, so you’ll have to intuit those elsewhere.

Filed Under: Data analysis, Data science Tagged With: correlation, game, statistics

Spreadsheet error delays opening of children’s hospital

October 26, 2020 By editor

An audit report has blamed a spreadsheet "copy and paste" error for cost overruns and delays at an Edinburgh children’s hospital.

A local politician called it

[…] one of the most expensive typos in history.

How many more high-profile spreadsheet failures is it going to take before we deem the inappropriate use of them to be professional malpractice?

Filed Under: Data analysis, Software Tagged With: spreadsheet abuse, spreadsheets

16,000 coronavirus cases missed by Excel

October 5, 2020 By editor

When the lead story in the Daily Mail complains about Excel misuse in its headline you know things have gone too far.

15,841 coronavirus cases were excluded from UK government figures as a result of

…an Excel spreadsheet reaching its maximum file size, which stopped new names being added in an automated process.

Apparently these details were not supplied to the "track and trace" programme, meaning that people exposed to the virus were not alerted—potentially leading to unnecessary infections.

I’ve been complaining about spreadsheet misuse for a decade, and this is one of the most shambolic examples I’ve come across. Blatant abuse of Excel as a ramshackle database.

This also highlights the dangers of casual automation. Without appropriate checks and balances, automated processes can fail catastrophically, and silently.

There really is no excuse for this level of incompetency. And, the worst thing is the "solution".

The technical issue has now been resolved by splitting the Excel files into batches.

Add more sticking plaster to the homespun system and press on. I can only weep.

Some additional technical details have been revealed since the story broke.

Filed Under: Data analysis Tagged With: Excel, spreadsheets

Data visualisation design guidelines

July 28, 2019 By editor

As companies start to take data more seriously we are seeing more of them publishing data design guidelines. Three comprehensive examples are

  • Greater London Authority
  • Office for National Statistics
  • The Cato Institute

Consider adopting one of these if your organisation is just starting to get into data visualisation—or if your existing charts aren’t up to scratch.

Filed Under: Data analysis Tagged With: data-viz, visualization

  • « Previous Page
  • 1
  • 2
  • 3
  • 4
  • 5
  • …
  • 17
  • Next Page »

Copyright © 2026 · Decision Mechanics Limited · info@decisionmechanics.com